RL fine-tuning for code generation
GRPO fine-tuning of Qwen2.5-Coder with unit-test rewards and a sandboxed executor. Lifted 1.5B pass@1 by +3.2 on MBPP and +5.5 on HumanEval+ (3 seeds), with no reward hacking across 21 audited runs.
- Type
- Build
- Tracks
- LLMs · ML
- Context
- TRL · LoRA · vLLM
- Links
- Code ↗
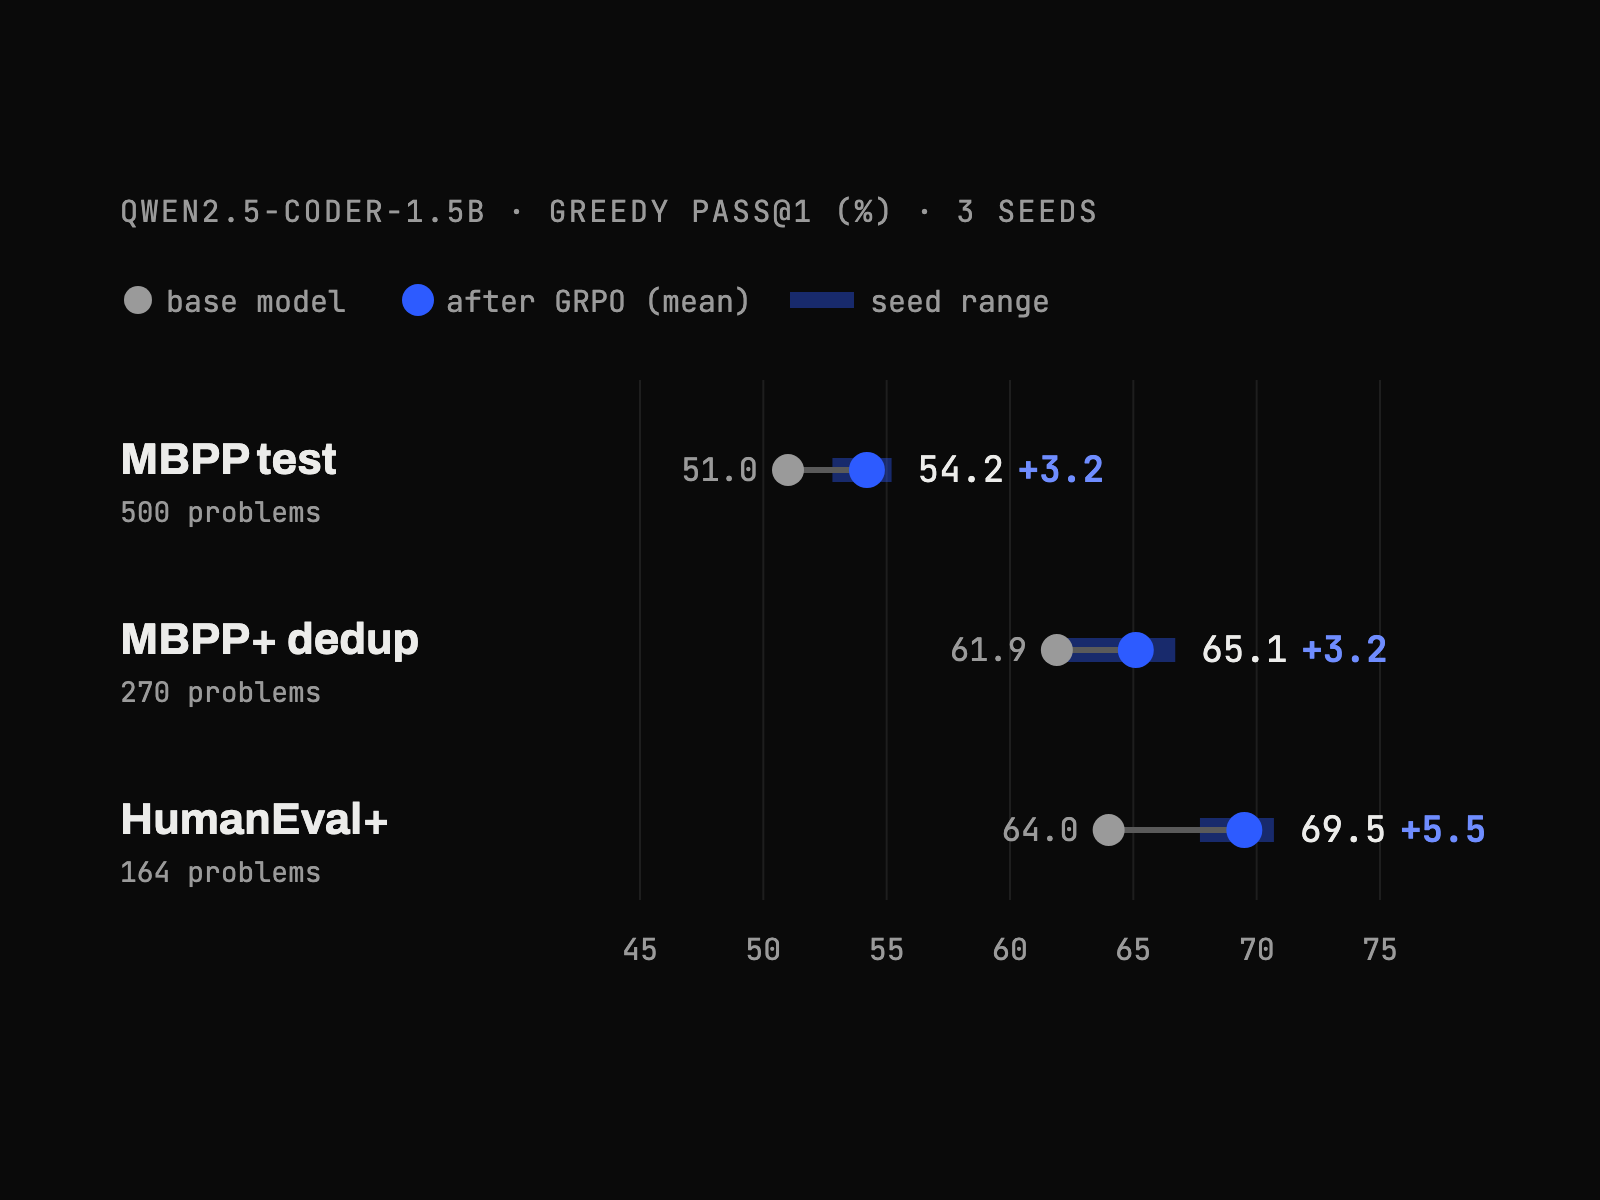 FIG. 05